Is My Backtest Overfit? We Ran the Gauntlet on Our Own Strategies
A backtest is overfit when it describes the past instead of an edge. The clean way to find out is to run a few standard tests, and the honest way is to run them on your own system and publish what they say. We did that on our four NQ strategies. On their own trades, three of the four come back statistically soft: their Harvey-Liu t-stats sit below 3.0, the rough line for "this looks real." We trade all four anyway, because together they clear that line with room to spare, and every one of the four made money in 2026 to date. Assembling a book out of edges too marginal to stand alone is the whole of how to build a profitable NQ strategy.
Below are the tests that matter, the t-stat for each strategy, and why three strategies that look soft alone still earn their seat. The book as a whole clears the 3.0 significance hurdle with room to spare, so the softness is at the strategy level, not the portfolio level. We measure every t-stat on the same per-trade ruler, so the strategy numbers and the book's t-stat are directly comparable.
Whose trades are these (read this before using our numbers)
Everything below is measured on our own book: four systematic NQ strategies that run together, one position at a time (we call the combined four "the book"). TradingView backtests from November 2011 to November 2026 (data as of November 6, 2026), 1 or 2 NQ minis a trade (2 when daily ranges are small, 1 when they are large; at today's index level every trade since July 2024 has been 1 contract), commissions and slippage included, $696,892 net over 3,139 trades. The entries are momentum and trend-continuation, intraday plus one overnight model. They are not mean reversion and not scalping.
That style shapes the test results. A momentum book lives or dies on a handful of big trending moves, which makes its statistics noisier and its overfit tests harder to pass than a high-win-rate system would be. Our exact t-stats describe our system. The method, running these tests on your own strategy before you trust it, transfers to any trader, including a discretionary one who wants to know whether a rule is real or just a story the chart told. The numbers themselves do not transfer.
What is overfitting in a backtest?
Overfitting, also called curve fitting, is turning enough dials that a rule fits past noise instead of signal. An overfit strategy looks brilliant in the backtest and falls apart on new data.
A strategy has thousands of dials: entry time, stop width, which indicator, what threshold. Turn enough dials and you can make almost any rule look great on past data, because you are fitting the noise, not the signal. That is overfitting, also called curve fitting. The tell is simple. An overfit strategy looks brilliant in the backtest and falls apart the moment it meets new data.
So the question "is my backtest overfit?" really means: how much of this result is edge, and how much is me having tried a lot of things until one looked good? You cannot answer that by staring at the equity curve. A curve-fit strategy and a real one can have the same beautiful curve. You answer it with tests built to punish the trying.
Which tests show whether a backtest is overfit?
Four carry most of the weight: the Harvey-Liu t-stat above 3.0, the Deflated Sharpe Ratio, walk-forward or out-of-sample testing, and the Probability of Backtest Overfitting, where under 20% is the usual pass.
There are dozens of overfit checks. Four carry most of the weight, and each attacks the problem from a different side.
The Harvey-Liu t-stat. This is the headline test. The t-stat measures how far your average result sits from zero, scaled by how noisy your results are. A high t-stat means the profit is unlikely to be luck. Campbell Harvey and Yan Liu, in their 2014 paper on the flood of published trading "factors," argued that the usual bar of 2.0 is far too soft once you account for how many strategies people test before publishing one. Their tougher line is t-stat above 3.0. We use 3.0 as the pass mark, same as they recommend.
The Deflated Sharpe Ratio (DSR). A Sharpe ratio (return divided by how bumpy that return is) rewards smooth returns, but it is easy to inflate by testing many variations and reporting the best one. The DSR, from Marcos Lopez de Prado, takes your Sharpe and deflates it by how many configurations you tried and how skewed and fat-tailed your returns are. It answers: given all the trying, what is the chance this Sharpe is genuinely above zero? Higher is better. A whole diversified book can push it toward 100%, but a single optimization-heavy strategy rarely gets there.
Walk-forward, also called out-of-sample testing. Split history into a part the strategy was built on (in-sample) and a part it never touched (out-of-sample). If the edge only shows up in-sample, it was fit to that period. A real edge keeps working out-of-sample. This is the most intuitive test and the hardest to fake. If you only ever run one of these, run this one.
Probability of Backtest Overfitting (PBO). From the same Lopez de Prado line of work, this one is clever. It chops your history into many blocks, and across thousands of combinations it asks how often the configuration that looked best in-sample turned out below average out-of-sample. If your "best" settings are really just luck, they will flip to below-average a lot. PBO is the share of times they do. Lower is better; under 20% is the usual pass.
Passing all four does not promise a strategy will make money. It only lowers the odds you are fooling yourself.
No single test proves an edge. The t-stat asks if profit beats luck, the Deflated Sharpe punishes you for trying many versions, walk-forward demands it work on unseen data, and PBO checks whether your best settings were a fluke. We ran the t-stat and the Deflated Sharpe on our own strategies and the book passed both, even though, as the next section shows, three of the four strategies did not clear the t-stat line on their own. Walk-forward is the one we cannot fully claim yet for the rules we trade now, and the 2026 section below says why.
Does each NQ strategy clear the 3.0 t-stat hurdle on its own?
No. Measured on its own trades inside the book, only Trend clears it, at 3.15. Overnight, VWAP Short and Opening Range Break sit between 2.09 and 2.93.
Here is the part most signal sellers would bury. When we run the gauntlet on each strategy's own trades, on the same per-trade ruler the book uses, only one of the four clears the t-stat-above-3 line. The other three fall short. The last column shows the profit factor (gross wins divided by gross losses; above 1.0 means the strategy made money) in 2026 to date, January 1 to November 6.
| Strategy | Direction | t-stat | 2026 profit factor |
|---|---|---|---|
| Trend | Long | 3.15 | 1.23 |
| Opening Range Break | Long | 2.09 | 1.42 |
| VWAP Short | Short | 2.56 | 2.49 |
| Overnight | Long | 2.93 | 1.28 |
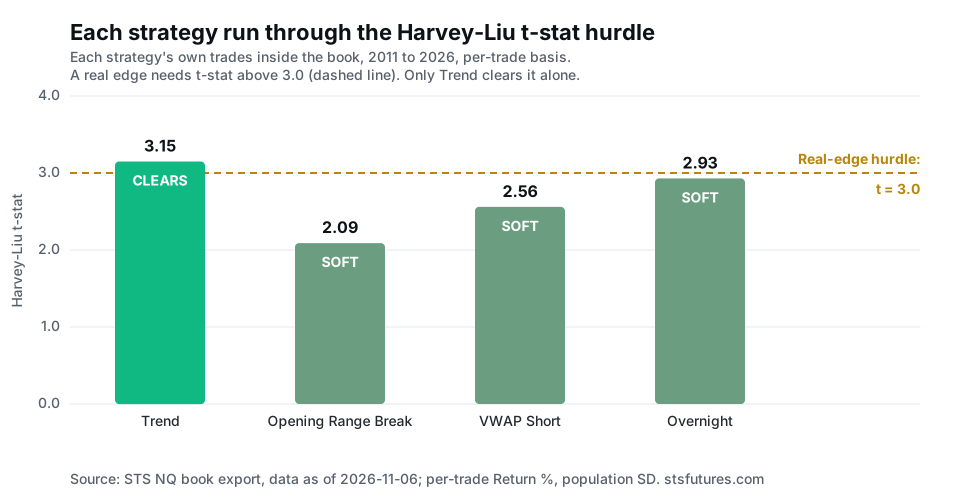
Notice the short. Earlier versions of this book leaned on a fragile short sleeve that only paid off in crashes. We removed it. The short that remains here is a convex, below-VWAP momentum short. On its own trades its t-stat is a soft 2.56, and its profit factor by four-year era swings from 0.92 to 2.33. Yet it has the highest 2026 profit factor of the four, 2.49, on just 18 trades. That gap is the whole lesson: a low solo t-stat does not mean no edge, it means a noisy one that leans on the rest of the book. Only Trend, at 3.15, clears the line alone. Read plainly: three of these four are optimization-sensitive on their own. None is fabricated, but none except Trend is a bulletproof, bet-the-house standalone edge.
Can a strategy with a weak t-stat still belong in a portfolio?
Yes, if the book is worse without it. Opening Range Break is our softest at 2.09, yet taking its trades out of the record cuts the book's Sharpe from 1.27 to 1.18.
If three of the four fall short of the t-stat line alone, why are they still running? Because the test they fail is the solo test, and we do not trade these strategies solo. They run together, one position at a time, and the value of a strategy inside a portfolio is not the same as its value alone.
Take Opening Range Break, the softest of the four at 2.09. It buys a confirmed breakout of the 9:30 to 9:45 opening range, a different setup from the other three. A simple check shows what it adds. Take its trades out of the record, leave every other trade as it was, and the book's Sharpe falls from 1.27 to 1.18 and its net from $696,892 to $500,476. The same is true of every strategy: drop any one of the four and the Sharpe falls, to between 1.10 and 1.22. It is a rough check, because with one strategy gone another might have taken some of those slots, but the direction is clear. There is a cost too, and we show it. Dropping any one strategy would have made the book's worst closed-trade drawdown a little smaller, between $23,286 and $25,220 against $25,342. Each one adds far more to the net than to the worst drawdown.
That is the portfolio lesson under all of this. A strategy can look statistically weak by itself and still lift the whole book, because the test rewards solo profit, not what a strategy adds next to the others. Drop the three soft strategies and you do not have a safer book, you have Trend alone. Trend's own trades show a Sharpe of 0.81 against the book's 1.27 on the same basis, and Trend clears the 3.0 line by a far thinner margin than the book does. We keep all four.
How did the four strategies do in 2026?
All four made money from January 1 to November 6, 2026, with profit factors from 1.23 for Trend to 2.49 for VWAP Short. The samples are small, 18 to 70 trades each, and for the rules we trade now this is a recent-period check, not a true out-of-sample test.
The single most convincing overfit test is also the simplest: does it work on data you did not build it on? A true out-of-sample window is a stretch of history the strategy could not have been fit to. For the rules we trade now, 2026 is not that. Their final rules and sizing were set in November 2026, with this year's data already in view, so we cannot honestly call it unseen. We still measured each strategy across it, because a strategy that had stopped working would show it here first.
All four made money. Including the three that look soft on the solo t-stat.
| Strategy | 2026 profit factor | Made money? |
|---|---|---|
| Trend | 1.23 (70 trades) | Yes |
| Opening Range Break | 1.42 (46 trades) | Yes |
| VWAP Short | 2.49 (18 trades) | Yes |
| Overnight | 1.28 (19 trades) | Yes |
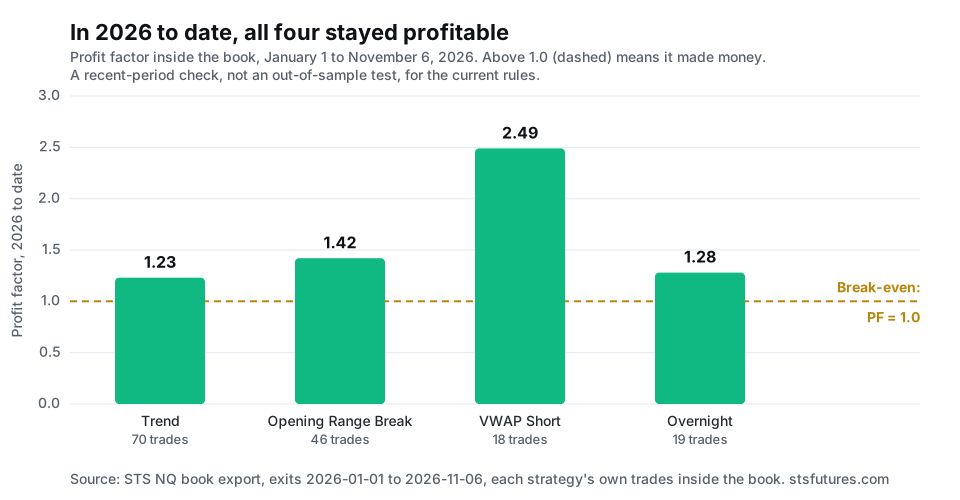
These are small samples, 18 to 70 trades each in this window, so read them as a check, not a verdict. The highest, VWAP Short at 2.49, sits on the fewest trades, so lean on it least. The soft strategies are soft, not broken. The only data the current rules have truly never seen is the trades still to come.
Does the combined book pass the overfit tests?
Yes on the significance tests. The portfolio clears the 3.0 hurdle, passes the 90% Deflated Sharpe threshold, and its profit factor by four-year era rises 1.05, 1.21, 1.37, 1.73.
Put the four together and the picture flips. The book holds one position at a time, the strategies take different setups at hours that run from the opening bell to the evening session, and the longs and the short do their damage in different conditions. So the combined book is far steadier than any single piece. Each strategy's own trades show a Sharpe between 0.67 and 0.89; the book's is 1.27 on the same basis.
The portfolio clears the 3.0 significance hurdle comfortably, and it still clears it with any one strategy taken out. The book Deflated Sharpe passes the >90% robustness threshold, after deflating for a high trial count. The edge has also strengthened over time, not faded: the book's profit factor by non-overlapping four-year era rises 1.05, 1.21, 1.37, 1.73 from the 2011-2014 block to 2023-2026. Our beta to buy-and-hold NQ is withdrawn pending re-derivation, so we are not quoting it here. No single strategy shows that whole profile alone. The diversification is doing real work, and these tests are how we measure it.
This is also why we do not sell individual strategies. A single sleeve is an ingredient. The product is the diversified book, because that is the thing the statistics actually support.
Can trying to improve a strategy make it overfit?
Yes. We once ran a long series of backtests trying to improve our short strategy, and every variation that looked healthier on its own hurt the portfolio.
Two stories from our own logs make the point harder than any test does.
We once ran a long series of backtests trying to improve our short strategy: different stops, exit times, entry triggers, volatility filters, sizing schemes. Nothing beat the production version inside the book. Several variations looked healthier on their own and every one of them hurt the portfolio. That is overfitting caught in the act. The "improvements" were fitting the past, and the discipline of testing them inside the full book, not alone, is what exposed them. All that trying is also why we deflate the Sharpe by a high trial count. Every one of those attempts is a reason to trust a single pretty result less.
The second is a bug. In June 2026 we found the book, as it ran then, was firing two trades on a single bar when it should hold one position at a time. We fixed it. The fix cut the backtested profit, because honoring one position at a time means turning down trades the buggy version took. We could have quietly kept the bigger number. We changed the number instead. A backtest you are willing to make worse for the sake of accuracy is a backtest you can trust a little more.
What to do with this
To check your own strategy, do not trust the equity curve and do not trust a single test. Run the four together. Hold the t-stat to 3.0, not 2.0. Deflate your Sharpe by the number of versions you actually tried, and be honest about that count. Carve off the most recent stretch of history, never let the strategy see it, and check that the edge survives. And if you ran a parameter sweep, run PBO to see how often your best settings would have flopped out-of-sample. One more cheap check is to point the same rules, unchanged, at a different instrument, which is what we did on ES, YM, and RTY with a previous version of our rules in our test of the NQ system on every index.
Then judge each piece at the level it lives at. A strategy can fall short of the solo test and still earn its seat in a portfolio, the way our Opening Range Break strategy does, but only if you can show the book is worse without it. If you cannot show that, the weak strategy is probably just weak, and the honest move is to simplify it or set it aside. See how the four fit together in our NQ trading strategies, or read the stop-width study for another case where the obvious backtest answer was the overfit one.
How we measured this
Instrument: CME Nasdaq-100 E-mini (NQ), $100,000 initial capital, no compounding, 1 or 2 NQ minis a trade (2 when daily ranges are small, 1 when they are large; at today's index level every trade since July 2024 has been 1 contract). Data: our four-strategy book on TradingView, November 2011 to November 2026 (data as of November 6, 2026), 3,139 combined trades. The per-strategy figures use each strategy's own trades inside the book, not separate solo backtests; the t-stats (per-trade percent-return basis, the same ruler as the book's t-stat, so the two are directly comparable) and the 2026 profit factors sit on that same basis. The check that drops one strategy removes that strategy's trades from the record and leaves every other trade unchanged; the Sharpe in it is on the same daily basis as the book's 1.27.
The tests have honest limits. The Deflated Sharpe depends on an assumed number of configurations tested; we report the t-stat (which does not) as the primary verdict, and the book Deflated Sharpe (which passes the >90% robustness threshold) uses a high trial count (3,000) so the deflation is conservative, not flattering. It still passes at 10,000. The 2026 window (January 1 to November 6) is short, and the current rules and sizing were set with it in view, so it is a recent-period check, not proof, and the per-strategy samples in it are small (18 to 70 trades each). These are hypothetical backtest results, not live fills. Our trade-level history, with entry times and prices, is proprietary, so we do not publish it, but the result of every trade is in our downloadable trade list, the methods reproduce on any trade list, and our book-level numbers reconcile to the full tear sheet and the strategy page. The same gauntlet results sit alongside the live record on our NQ futures signals page. Plans are on the pricing page.
We trade this book live and sell access to the signals, so judge the data accordingly. This article is educational and is not investment advice. Futures trading involves substantial risk of loss and is not suitable for every investor.
Hypothetical performance disclaimer (CFTC Rule 4.41): hypothetical or simulated performance results have certain limitations. Unlike an actual performance record, simulated results do not represent actual trading. Also, since the trades have not been executed, the results may have under- or over-compensated for the impact, if any, of certain market factors, such as lack of liquidity. Simulated trading programs in general are also subject to the fact that they are designed with the benefit of hindsight. No representation is being made that any account will or is likely to achieve profit or losses similar to those shown. Past performance does not indicate future results.
See our forward record, every live signal we have sent, dated and public.